A local LLM on a Pi 5
A Raspberry Pi 5 on Ubuntu with an LLM-8850 M.2 accelerator running AXERA's quantized Qwen2.5-0.5B: 18.15–18.42 tok/s across three runs of one prompt, and a model that introduced itself as created by Anthropic.
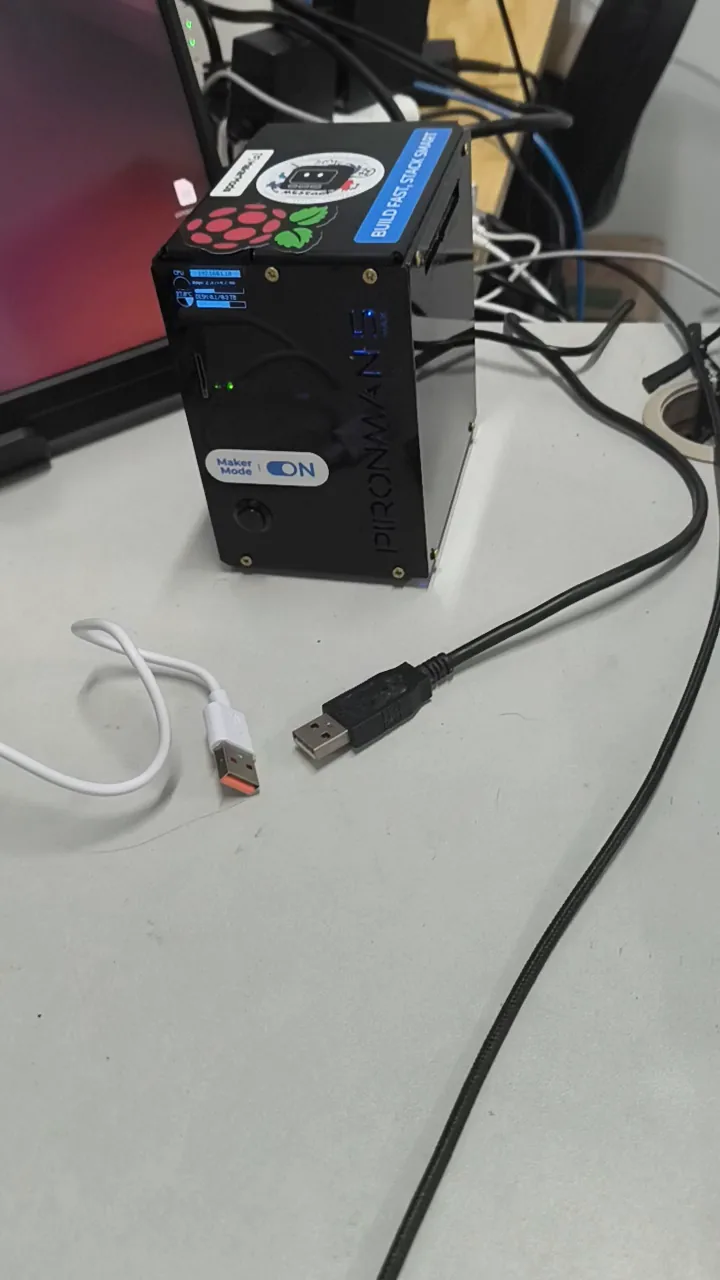
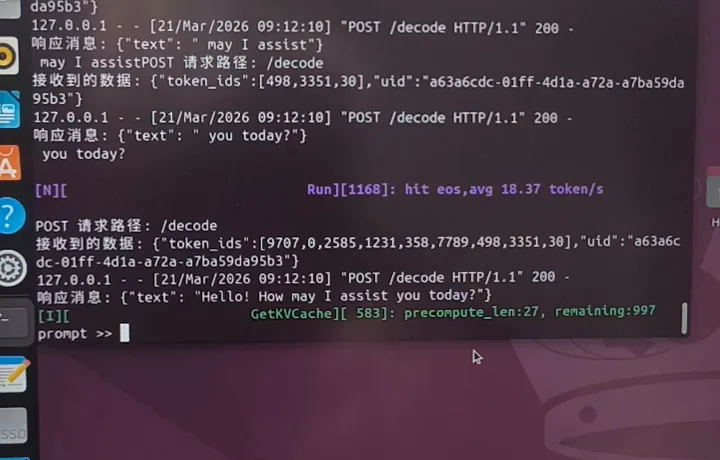
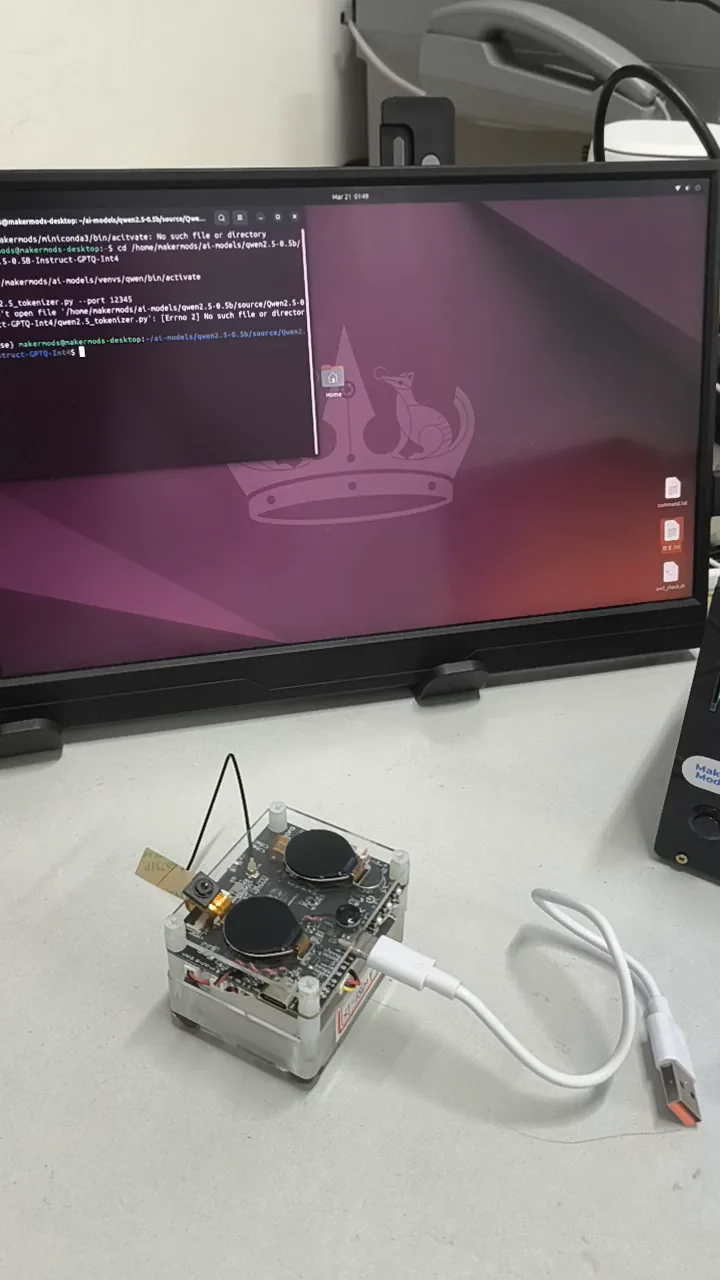
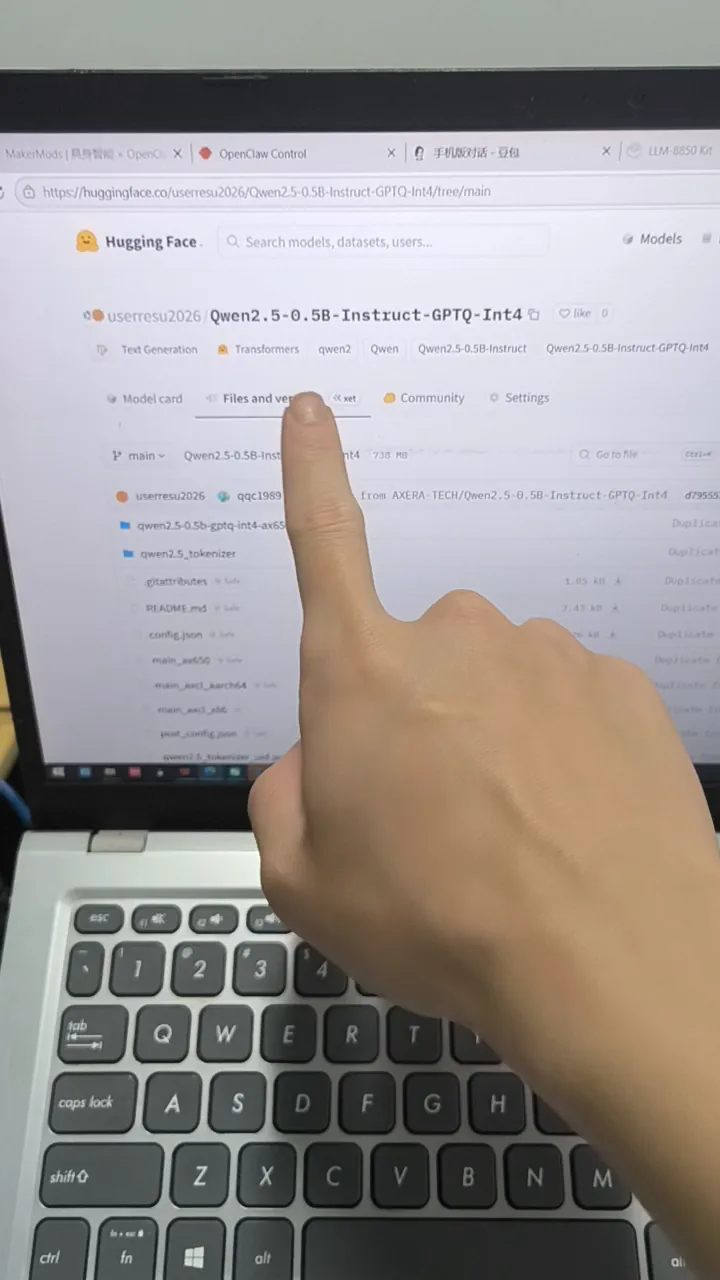
The machine is a Raspberry Pi 5 on Ubuntu, with an M5Stack LLM-8850 in the M.2 slot (M.2 M-Key 2242, AXERA open SDK). The model is AXERA's converted Qwen2.5-0.5B-Instruct-GPTQ-Int4, served on `127.0.0.1:8080` with every request and reply printed to the terminal.
Measured numbers
The load log shows `AXCLWorker start with devid 0`, a run of `init N axmodel ok`, and 6454 MB left on the card. One prompt, three consecutive runs, each closing with `hit eos, avg … token/s`: 18.42 / 18.15 / 18.37. Those are this board, this quant and this context length — not a promise for other hardware.
It got its own name wrong
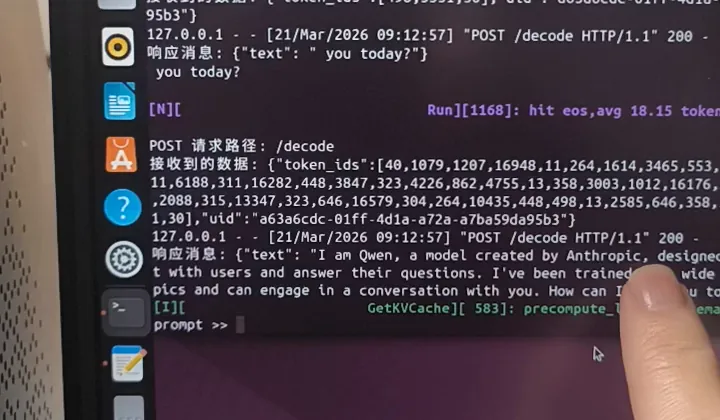
`system_prompt` says `You are Qwen`, and the model still answered: I am Qwen, a model created by Anthropic, designed to interact with users and answer their questions. A 0.5B model does this; I left the sentence in the footage rather than edit it out.
Its own failures
The earliest output was just a `{"token_ids": [...]}` array with the front end printing token IDs as text; that was fixed later. It also hit `save_kvcache failed` — the KV cache could not be written to a read-only directory, so the server kept running but recomputed the prefix every time.
One question
Test question: the car wash is 50 m from home — drive or walk? The model said drive. Sent the log to a cloud model for review, and it locked onto the model's phrasing instead of the 50 m — same question, and the two models are wrong in different places.
Experiments describe their actual environment and scope. Check the linked source for implementation details, license, current support and reproduction steps.
 本地模型 · RTX 5060 Ti
Strata / Qwen3.8-Flash-Next
A 125B Qwen3.8-Flash-Next running on one RTX 5060 Ti: 16 GB VRAM, 64K context, 74–110 tok/s decode in a real session.
↗ 公开仓库
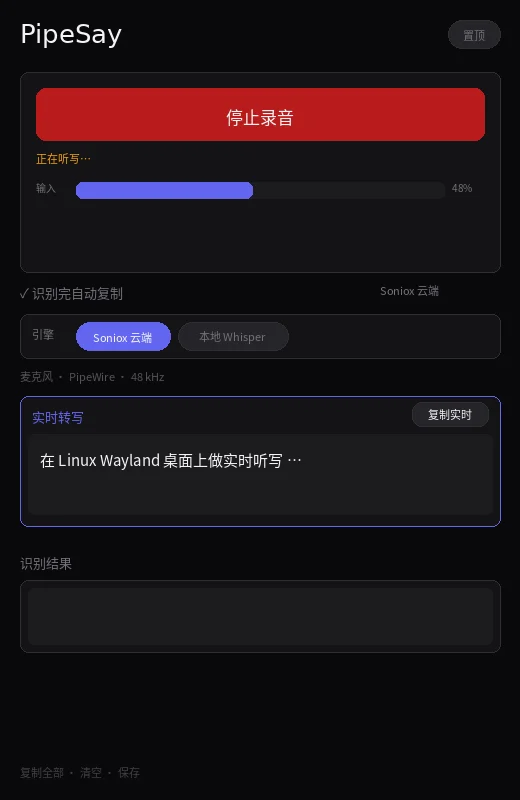
pipesay
Linux live dictation for Wayland — speak, see text, auto-copy. MIT.
↗ 实机推理
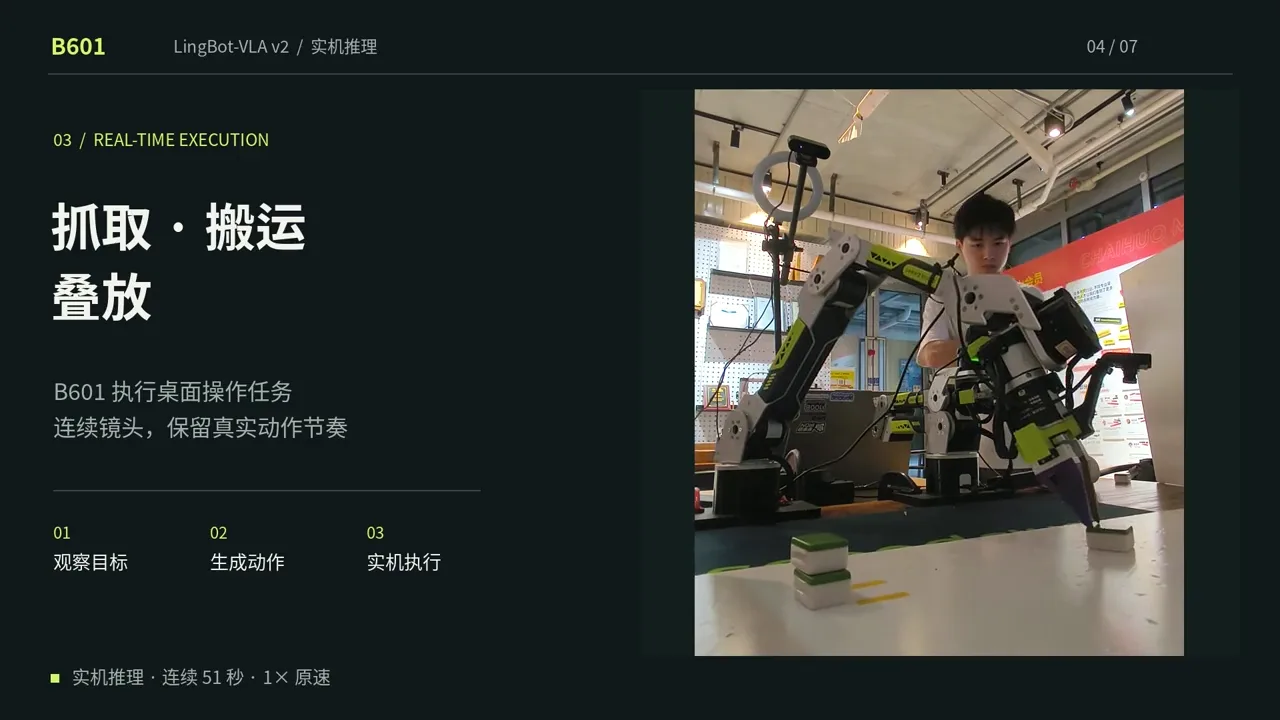
B601 × LingBot-VLA v2
Bringing teleoperation demos, VLA inference and real dual arm manipulation together on the B601.
↗